yahboom
HomeLearn
Solution
Blog
Online Store
About Us
EN/中文
AI View Depth camera📖
01.Linux basic course
  • 1.Introduction to Linux system
  • 2.Ubuntu file system
  • 3.Ubuntu common commands
  • 4.Ubuntu common editors
  • 5.Ubuntu software operation commands
  • 6.Virtual machine installation
  • 7.SSH remote control
  • 8.VNC remote control
  • 9.Transfer files remotely
  • 10.Driver library and communication
  • 11.Static IP and hotspot mode
  • 12.Bind device ID
  • 13.Capacity expansion and resource allocation
  • 14.Update system software sources
  • 15.Set root user password
  • 16.sudo free password
  • 17.Connect to WiFi network
  • 18.View system version
  • 19.Customized service management
  • 20.Back up system image
02.ROS1-camera usage course
  • 1. Camera usage instructions
  • 2. Environment Construction
  • 3. Camera recording video
03.ROS1-OpenCV course
  • 1.Opencv Source CV Introduction
  • 2.Image reading and display
  • 3.Picture writing
  • 4.Picture Quality
  • 5.Pixel Operation
  • 6.Picture scaling
  • 7.Picture cutting
  • 8.Picture translation
  • 9.Picture mirroring
  • 10.Affine transformation
  • 11.Picture rotation
  • 12.Perspective transformation
  • 13.Grayscale processing
  • 14.Image binarization
  • 15.Edge detection
  • 16.Line segment drawing
  • 17.Rectangle and circle drawing
  • 18.Text and picture drawing
4.ROS1-basic course
  • 1.ROS introduction
  • 2.ROS installation
  • 3.ROS common command tools
  • 4.ROS workspace
  • 5.ROS function package
  • 6.ROS node
  • 7.ROS topic publisher
  • 8.ROS topic subscribers
  • 9.ROS service client
  • 10.ROS service server
  • 11.ROS action client
  • 12.ROS action server
  • 13.ROS custom message reception
  • 14.ROS-launch file
  • 15.ROS-TF transformation
  • 16.ROS parameter service
  • 17.ROS-rviz use
  • 18.ROS-rqt tool usage
  • 19.Topic message recording and playback
  • 20.urdf model introduction
  • 21.gazebo introduction
  • 22.ROS distributed communication
5.ROS1-Mediapipe course
  • 1.Hand detection
  • 2.Posture detection
  • 3.Overall detection
  • 4.Face detection
  • 5.Face recognition
  • 6.Face effects
  • 7.3D object recognition
  • 8.Brush
  • 9.Finger control
  • 10.Gesture recognition
6.ROS+Opencv application
  • 1.Camera calibration
  • 2.QR code
  • 3.Human body pose estimation
  • 4.Target detection
  • 5.ROS+Opencv basics
  • 6.Face recognition
  • 7.Harris corner detection
  • 8.Target tracking algorithm
  • 9.Contour moment
  • 10.Polygon outline
  • 11.Discrete Fourier transform algorithm
  • 12.Edge detection algorithm
  • 13.Face detection algorithm
  • 14.Optical flow detection algorithm
  • 15.Contour detection
  • 16.General contour detection
  • 17.Feature point tracking
  • 18.HLS color filtering
  • 19.Hough circle detection
  • 20.Hough line detection
  • 21.HSV color filtering
  • 22.LK optical flow algorithm
  • 23.Human body detection algorithm
  • 24.Phase-related displacement detection
  • 25.Image pyramid sampling algorithm
  • 26.RGB color filtering
  • 27.Clear background detection algorithm
  • 28.Simplified optical flow algorithm
  • 29.Simple filter
  • 30.Threshold image processing
  • 31.Watershed segmentation algorithm
  • 32.View point cloud data
  • 33.AR vision
  • 34.AR QR code tracking
  • 35.Color tracking
  • 36.Object tracking
07.ROS2-camera usage course
  • Instructions for using camera
08.ROS2-basic course
  • 1.Introduction to ROS2
  • 2.ROS2 install Humble
  • 3.ROS2 development environment
  • 4.ROS2 workspace
  • 5.ROS2 function package
  • 6.ROS2 node
  • 7.ROS2 topic communication
  • 8.ROS2 service communication
  • 9.ROS2 action communication
  • 10.ROS2 custom interface message
  • 11.ROS2 parameter service case
  • 12.ROS2 meta-function package
  • 13.ROS2 distributed communication
  • 14.ROS2 DDS
  • 15.ROS2 time related API
  • 16.ROS2 common command tools
  • 17.ROS2 rviz2 use
  • 18.ROS2 rqt toolbox
  • 19.ROS2 Launch startup file configuration
  • 20.ROS2 recording and playback tool
  • 21.ROS2 URDF model
  • 22.ROS2 Gazebo simulation platform
  • 23.ROS2 TF2 coordinate transformation
09.ROS2-OpenCV course
  • 1. ROS+opencv application
  • 2. QR code creation and recognition
  • 3. AR vision
10.ROS2-Mediapipe course
  • 1.Hand detection
  • 2.Posture detection
  • 3.Overall detection
  • 4.Face detection
  • 5.Personal insurance identification
11.ROS2-Depth camera course
  • 1. Use of depth camera
  • 2. Camera internal parameter calibration
  • 3. Color tracking
  • 4. KCF object tracking
  • 5. ORB_SLAM2 basics
  • 6. ORB_SLAM2 PCL mapping
  • 7. ORB_SLAM2 Octomap mapping
12.Bracket installation video
  • Bracket installation video
Download
  • VM_ROS1
  • VM_ROS2
  • Code-ROS1
  • Code-ROS2
  • 3D_File
  • ROS_Basic_VM
Download ZIP

Welcome to AI View Depth camera repository

4.Target detection

4. Opencv Application

4.1. Target Detection

The main problem solved in this section is how to use the dnn module in OpenCV to import a trained target detection network. However, there are requirements for the version of opencv.

Currently, there are three main methods for target detection using deep learning:

  • Faster R-CNNs

  • You Only Look Once (YOLO)

  • Single Shot Detectors (SSDs)

Faster R-CNNs is the most commonly heard neural network based on deep learning. However, this method is technically difficult to understand (especially for newcomers to deep learning), difficult to implement, and difficult to train.

In addition, even if the "Faster" method is used to implement R-CNNs (here R stands for Region Proposal), the algorithm is still relatively slow, about 7FPS.

If we pursue speed, we can turn to YOLO, because it is very fast, reaching 40-90 FPS on TianXGPU, and the fastest version may reach 155 FPS. But the problem with YOLO is that its accuracy needs to be improved.

SSDs was originally developed by Google and can be said to be a balance between the above two. Compared with Faster R-CNNs, its algorithm is more direct. Compared with YOLO, it is more accurate.

4.1.1, Model Structure

The main work of MobileNet is to replace the past standard convolutions with depthwise sparable convolutions to solve the problems of computational efficiency and parameter quantity of convolutional networks. The MobileNets model is based on depthwise sparable convolutions, which can decompose the standard convolution into a depthwise convolution and a point convolution (1 × 1 convolution kernel). Deep convolution applies each convolution kernel to each channel, while 1 × 1 convolution is used to combine the output of channel convolution.

Batch Normalization (BN) is added to the basic components of MobileNet, that is, at each SGD (stochastic gradient descent), the standardization process is performed so that the result (each dimension of the output signal) has a mean of 0 and a variance of 1. Generally, when the convergence speed is very slow or the gradient explodes during neural network training, BN can be tried to solve the problem. In addition, BN can also be added to speed up training and improve model accuracy in general use.

In addition, the model also uses the ReLU activation function, so the basic structure of the depthwise separable convolution is as shown in the figure below:
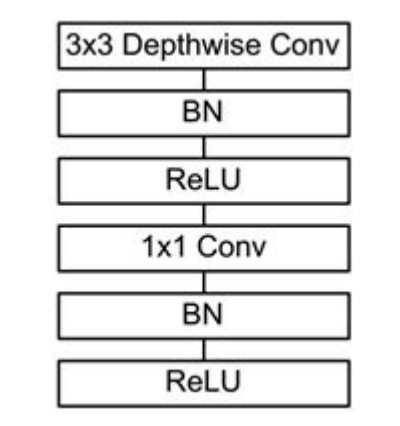
image-20231017173144555

The MobileNets network is composed of many depthwise separable convolutions shown in the figure above. The specific network structure is shown in the figure below:
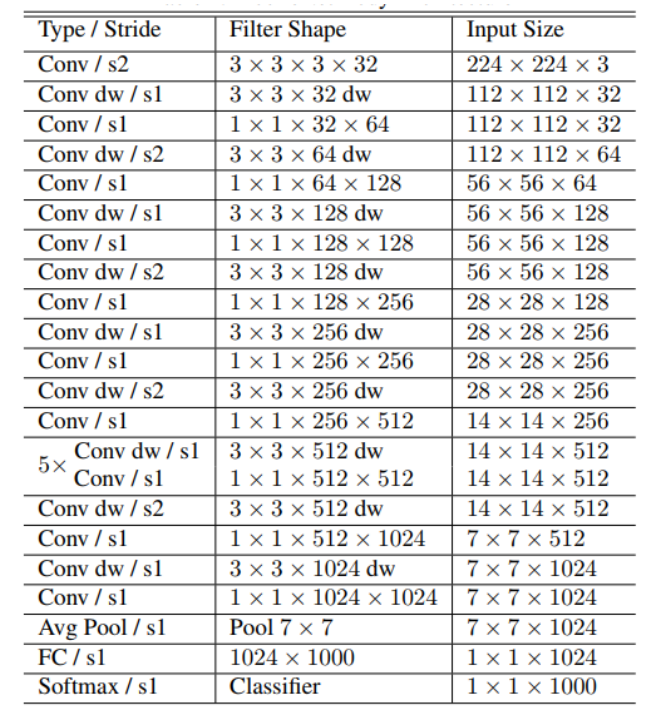
image-20231017173319284

4.1.2, Source code analysis

Source code location: ~/orbbec_ws/src/astra_visual/detection/target_detection.py

List of recognizable objects,

xxxxxxxxxx
[person, bicycle, car, motorcycle, airplane, bus, train, truck, boat, traffic light, fire hydrant, street sign, stop sign, parking meter, bench, bird, cat, dog, horse, sheep, cow, elephant, bear, zebra, giraffe, hat, backpack, umbrella, shoe, eye glasses, handbag, tie, suitcase, frisbee, skis, snowboard, sports ball, kite, baseball bat, baseball glove, skateboard, surfboard, tennis racket,bottle, plate, wine glass, cup, fork, knife, spoon, bowl,banana, apple, sandwich, orange, broccoli, carrot, hot dog,pizza, donut, cake, chair, couch, potted plant, bed, mirror,dining table, window, desk, toilet, door, tv, laptop, mouse,remote, keyboard, cell phone, microwave, oven, toaster,sink, refrigerator, blender, book, clock, vase, scissors,teddy bear, hair drier, toothbrush]

Load the category [object_detection_coco.txt], import the model [frozen_inference_graph.pb], specify the deep learning framework [TensorFlow]

xxxxxxxxxx
# load the COCO class names
with open('object_detection_coco.txt', 'r') as f: class_names = f.read().split('\n')
# get a different color array for each of the classes
COLORS = np.random.uniform(0, 255, size=(len(class_names), 3))
# load the DNN modelimage
model = cv.dnn.readNet(model='frozen_inference_graph.pb',config='ssd_mobilenet_v2_coco.txt',framework='TensorFlow')

Import the image, extract the height and width, calculate the 300x300 pixel blob, and pass this blob to the neural network

xxxxxxxxxx
def Target_Detection(image):
image_height, image_width, _ = image.shape
# create blob from image
blob = cv.dnn.blobFromImage(image=image, size=(300, 300), mean=(104, 117, 123), swapRB=True)
model.setInput(blob)
output = model.forward()
# loop over each of the detections
for detection in output[0, 0, :, :]:
# extract the confidence of the detection
confidence = detection[2]
# draw bounding boxes only if the detection confidence is above...
# ... a certain threshold, else skip
if confidence > .4:
# get the class id
class_id = detection[1]
# map the class id to the class
class_name = class_names[int(class_id) - 1]
color = COLORS[int(class_id)]
# get the bounding box coordinates
box_x = detection[3] * image_width
box_y = detection[4] * image_height
# get the bounding box width and height
box_width = detection[5] * image_width
box_height = detection[6] * image_height
# draw a rectangle around each detected object
cv.rectangle(image, (int(box_x), int(box_y)), (int(box_width), int(box_height)), color, thickness=2)
# put the class name text on the detected object
cv.putText(image, class_name, (int(box_x), int(box_y - 5)), cv.FONT_HERSHEY_SIMPLEX, 1, color, 2)
return image

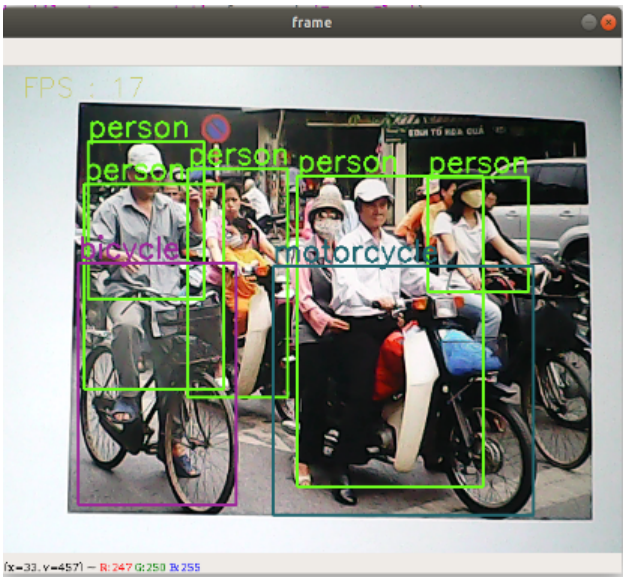
4.1.3, Start

Terminal input,

xxxxxxxxxx
cd ~/orbbec_ws/src/astra_visual/detection
python target_detection.py

image-20231017174447025

Human body pose estimation
ROS+Opencv basics

COMPANY

  • About us
  • Team Style
  • Blog

LEARNING & EXPLORATION

  • Tutorials
  • Edge AI hardware
  • Educational robots
  • Embedded intelligent hardware

WHERE TO BUY

  • Yahboom Online Store
  • Amazon
  • Alibaba
  • AliExpress
  • Mercado

TECHNOLOGY SUPPORT

  • Email: support@yahboom.com

BE A DISTRIBUTOR

  • Email: sales@yahboom.com
QR Code

Copyright © 2017-2026 Yahboom. All Rights Reserved.

EN/中文