Welcome to ROSMASTER A1 repository
9. Custom wake-up response
Custom wake-up response
1. Course Content
- Adding audio files to the multi_brains program audio library allows you to customize the wake-up voice response.
[!NOTE]
- This tutorial is only for users who need to customize personalized voice responses and does not affect normal use.
- If you do not need to customize personalized responses, you can skip this section.
2. Preparing Audio Files
Note: You need to copy the generate_voice file from the "Source Code" folder to the current board for testing. For Jetson Nano and Raspberry Pi 5 boards, you will need to use Docker.
- First, place the
generate_viocefile from the source code in the root directory. Then, place the command in the following path:
xxxxxxxxxxsudo cp generate_vioce /usr/local/bin/- You can prepare the audio material for the voice reply yourself.
- Alternatively, you can generate the voice using the system's built-in
generate_viocecommand. The voice generation model uses the Alibaba Cloud Model Studio Platform's speech synthesis model, so you need to configureALIYUN_API_KEYaccording to the tutorial in02-Configure API-KEYof this chapter first. - Pre-configure Alibaba Cloud Model Studio Platform API-KEY
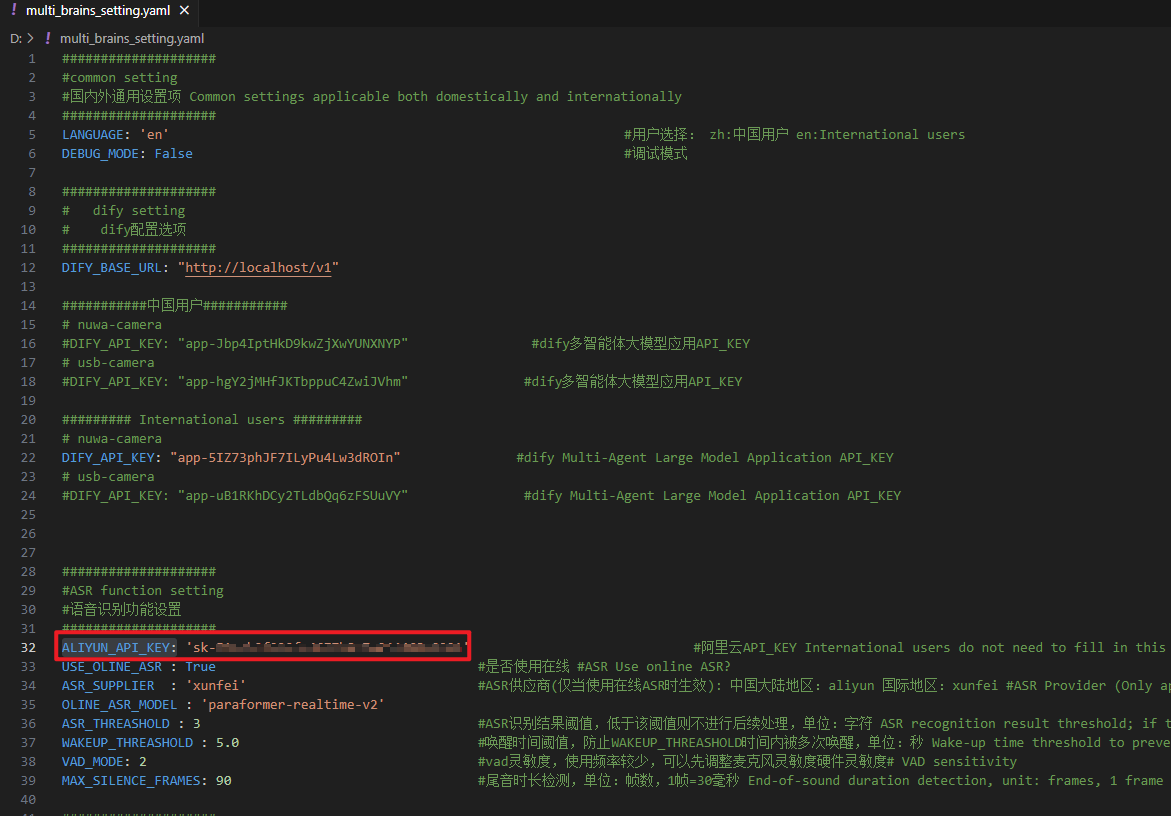
- Run the command in the terminal:
xxxxxxxxxxgenerate_vioce --text Hello --language_type English
- Where
--textis the startup parameter, "Hello" Replace with the content you want to synthesize the speech for.

- Audio files will be automatically saved in the
~/generate_voices/directory.
[!NOTE] Other optional startup parameters are as follows:
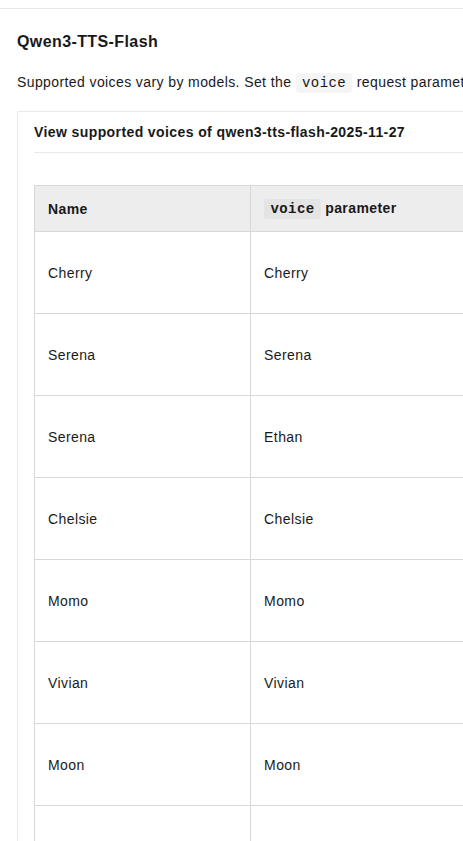
- --voice: Speaker, default
Cherry- --language_type: Language, specify the language of the synthesized audio. Available options include
Chinese,English,German,Italian,Portuguese,Spanish,Japanese,Korean,French, andRussian.- --save_path: Audio file save path, default
~/- --config_file: Configuration file path, default
~/yahboomcar_ros2_ws/yahboomcar_ws/src/multi_brains/config/multi_brains_setting.yaml- --text: Text to be synthesized audio, default is empty
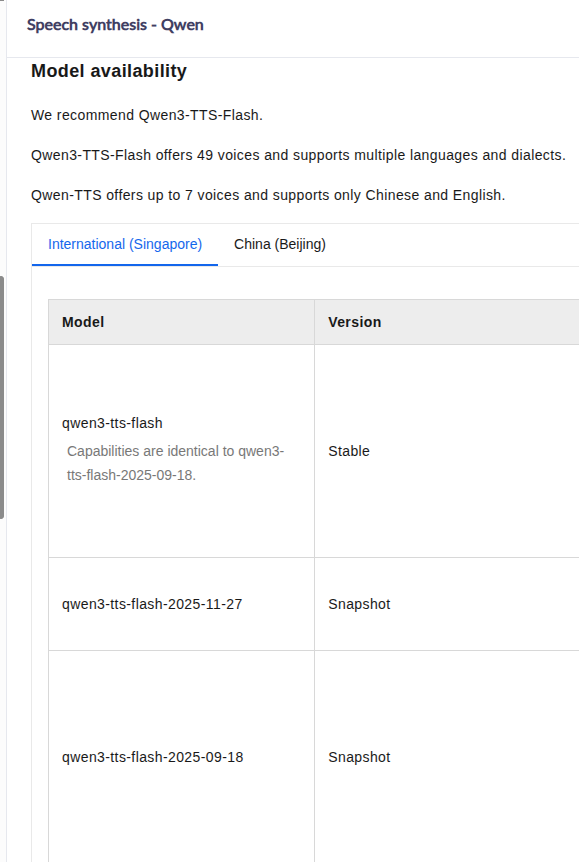
- --model The speech synthesis model defaults to
qwen3-tts-flash.
For available speakers and speech synthesis models, please refer to the dynamic notifications on the Bailian official website: https://bailian.console.aliyun.com/?spm=5176.29619931.J_SEsSjsNv72yRuRFS2VknO.2.74cd10d73l2Pw5&tab=doc#/doc/?type=model&url=2879134
- Reference Model:
- Reference Voice
- Supported Languages
Chinese, English, Spanish, Russian, Italian, French, Korean, Japanese, German, Portuguese
3. Loading Audio Files
- Multi_brains system audio path:
xxxxxxxxxx/home/jetson/
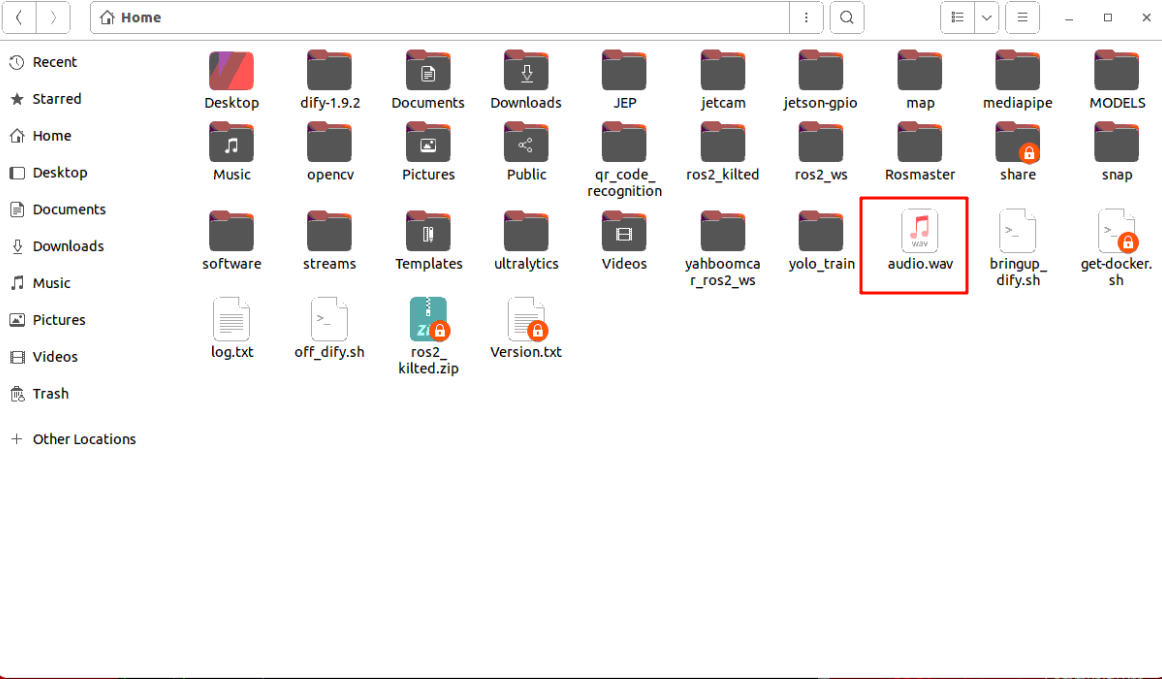
- Where:
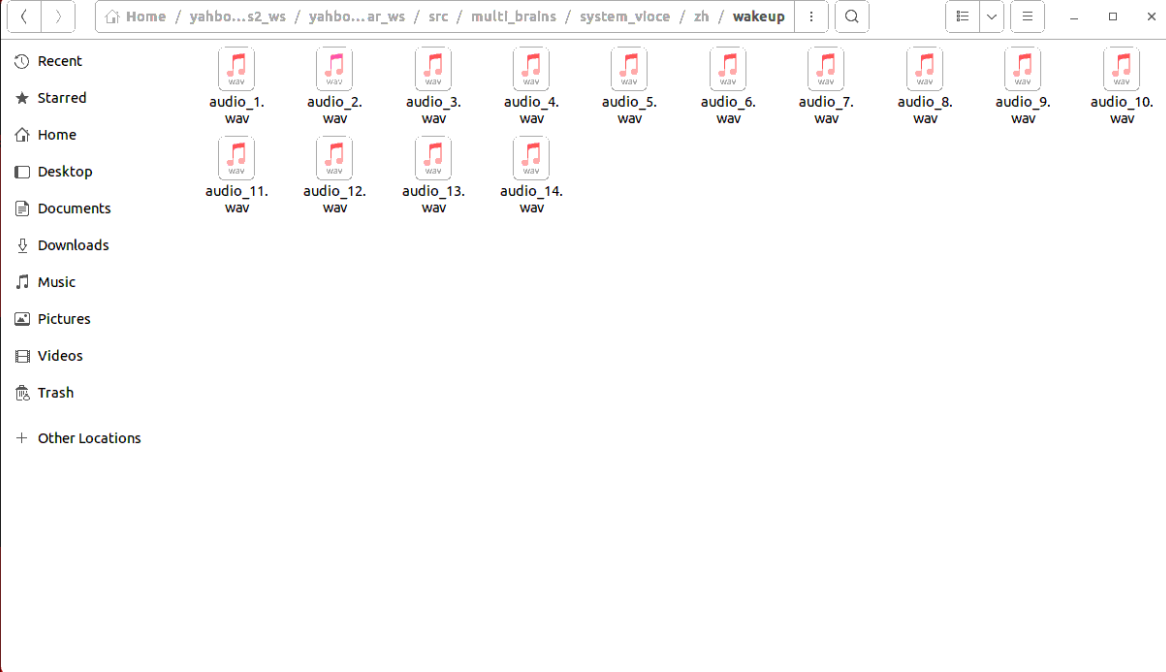
zhis the Chinese response audio, suitable for Chinese users. Place the prepared audio files in this directory:
xxxxxxxxxx~/yahboomcar_ros2_ws/yahboomcar_ws/src/multi_brains/system_vioce/zh/wakeup
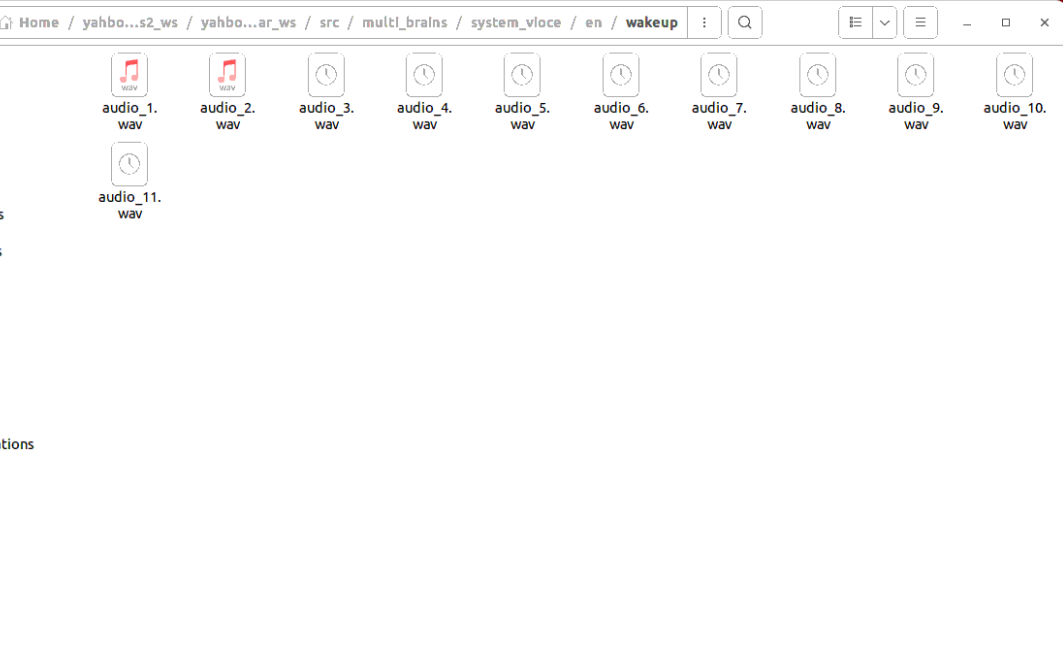
enis the English response audio, suitable for international users. Place the prepared audio files in this directory:
xxxxxxxxxx~/yahboomcar_ros2_ws/yahboomcar_ws/src/multi_brains/system_vioce/en/wakeup
- When the multi_brains program is launched, the audio file in the corresponding directory will be automatically loaded, and a personalized response voice will be randomly played when the user wakes up.