Welcome to RDK X5 Board repository
5. Camera Application
OpenClaw Camera Application Tutorial
Before starting, please complete [01-Peripheral Hardware Configuration], [02-OpenClaw API-KEY Configuration], [03-OpenClaw Model Switching], [04-OpenClaw Prompts], [05-AI Voice Interaction Configuration], and [06-Three Conversation Scheme Configuration and Testing] in the
Preparation for Usedirectory. This document assumes the basic environment is already prepared and only expands on camera-related content.
1. Tutorial Objectives
This tutorial demonstrates OpenClaw's natural language control capabilities through CSI camera peripherals. After completing this tutorial, readers will be able to:
Understand the basic idea of using a camera for photography and visual analysis in OpenClaw
Interact with OpenClaw via three methods: WhatsApp, TUI, and voice code
Complete four camera cases: photo archiving, scene description, OCR recognition, target localization and face detection
Understand the complete pipeline from "user proposes visual task" to "image capture" and "result return"
2. Hardware Preparation
OpenClaw main board
CSI camera module
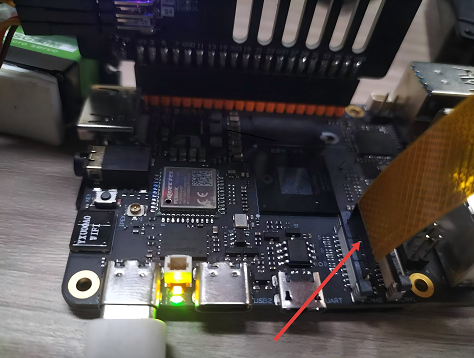
Camera ribbon cable
[Optional] Microphone moduleWiring diagram
3. Software Preparation
For international version:
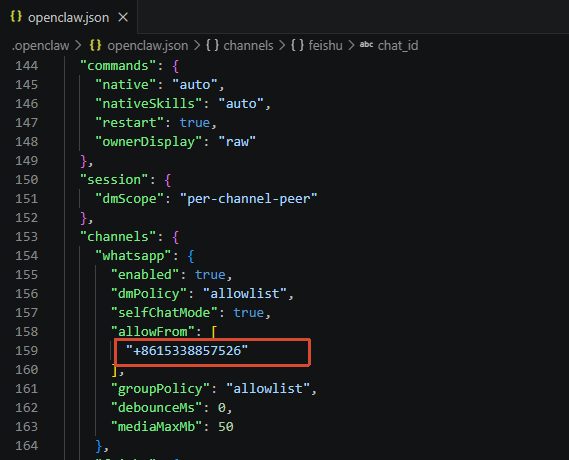
If you are using WHATSAPP and want to upload images directly to WhatsApp, you need to fill in the conversation ID of your newly created WhatsApp conversation in the "allowFrom" path below.
Open your newly created WhatsApp conversation to see the conversation ID.
Fill this into "allowFrom":
Enter the following command in the terminal to take effect:
openclaw gateway restart
4. Testing Camera Application
Before starting this tutorial, please complete a basic openclaw tui conversation self-check first; if you haven't done so, see [05-Three Conversation Scheme Configuration and Testing]. Also, please confirm that the visual model has been configured, refer to [02-OpenClaw API-KEY Configuration] and [03-OpenClaw Model Switching]. After passing, proceed to the camera-specific test.
Enter the following command in the terminal to enter TUI:
xxxxxxxxxxopenclaw tui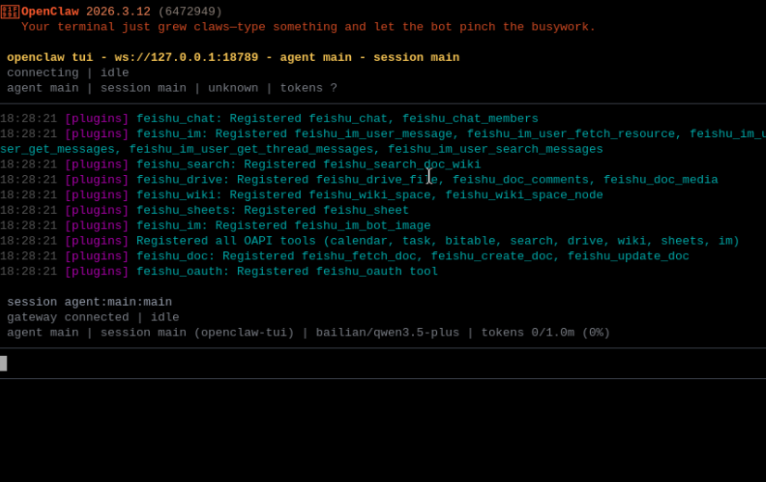
You can try entering the following content in the terminal:
Help me take a photo
Recognize the text in this image
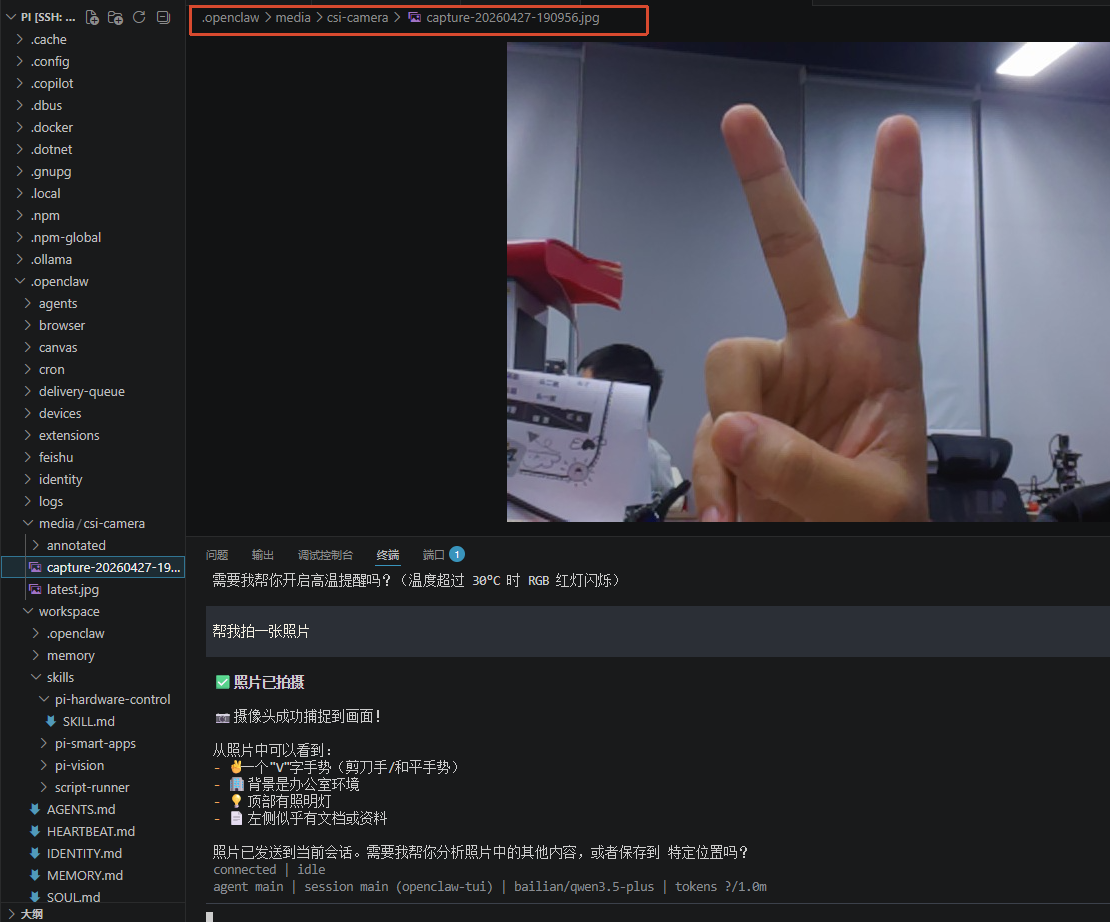
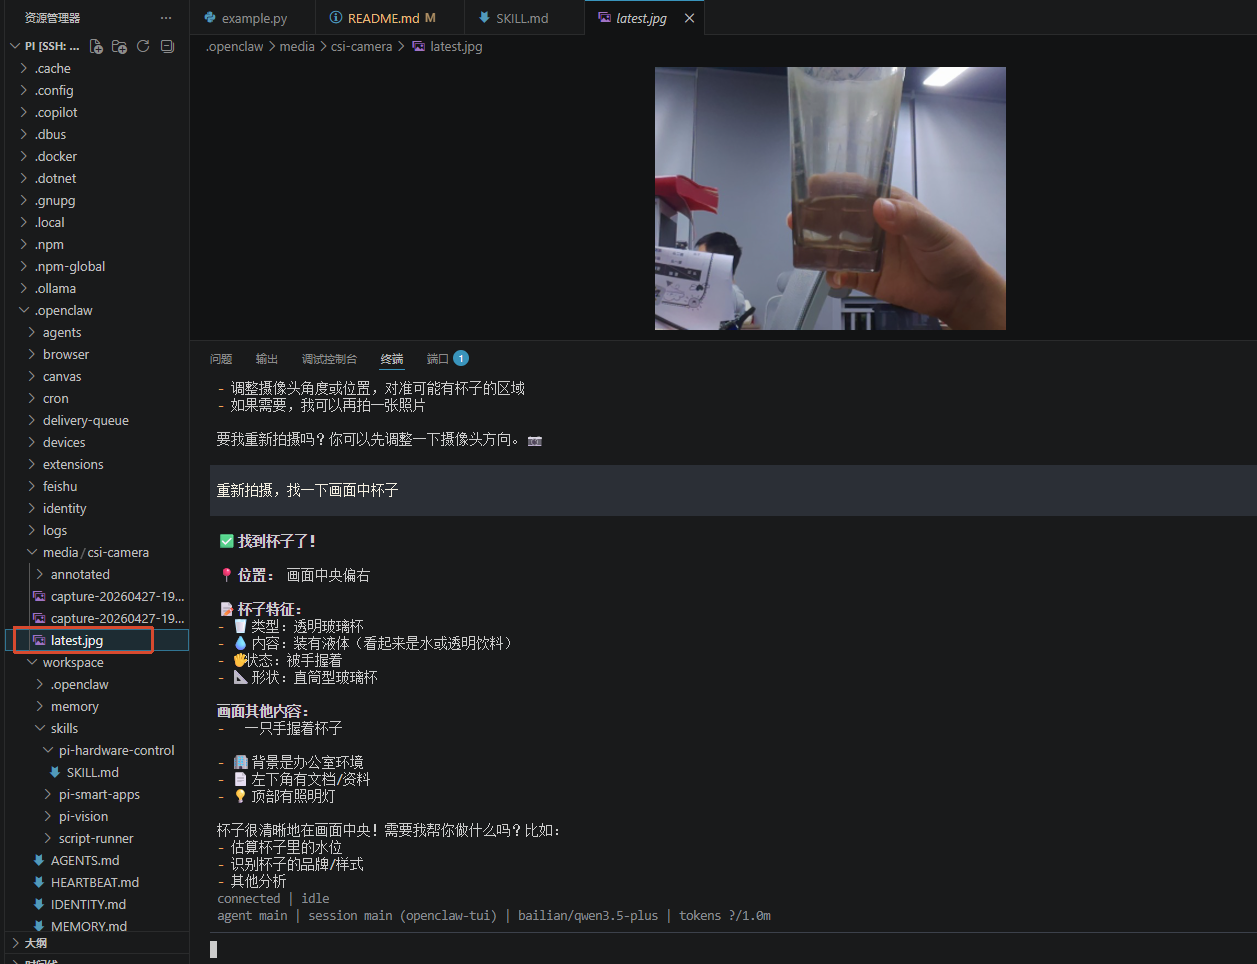
Find the cup in the frame (since the model will contact context, remind it to retake the photo, otherwise it might use the first photo)
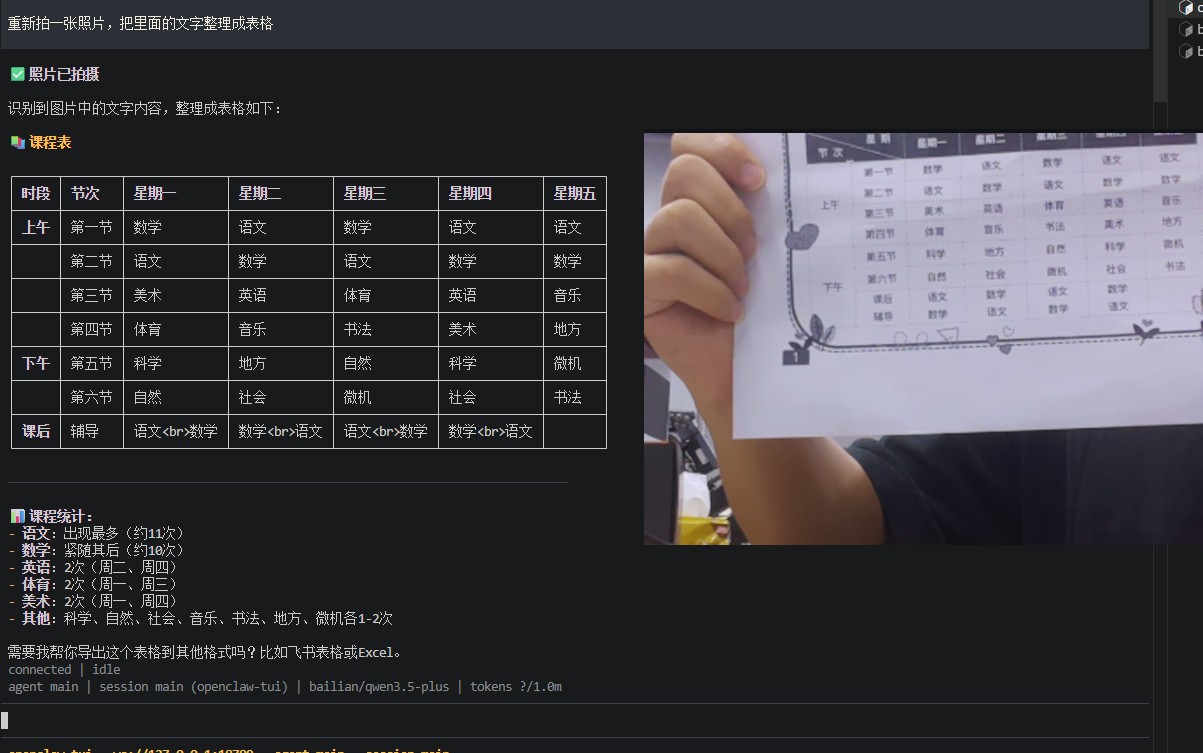
Retake a photo and organize the text inside into a table
5. Three Schemes for Conversing with OpenClaw
| Scheme | Suitable Scenarios | Advantages | Suggested Positioning |
|---|---|---|---|
| Remote control, classroom demonstration | Easy access, suitable for multi-user experience | Demonstrate "remote natural language control" | |
| TUI | Local debugging, command verification | Most direct, easiest to troubleshoot | Get the visual pipeline running first |
| Voice Code | Voice interaction, complete AI experience | Closest to real conversation experience | As the final demonstration scheme |
If you have selected the AI voice module + speaker, Feishu dialogue, tui, and WhatsApp dialogue need to broadcast the content of openclaw's reply. You can run the following program on the terminal. The AI voice module dialogue does not need to be run repeatedly
Modify whether to enable broadcast parameter
xxxxxxxxxx/home/sunrise/voice_to_openclaw/.env
xxxxxxxxxxENABLE_TTS=true # This parameter controls whether to broadcast. After modifying and saving, run the following program in the terminal.Enter in terminal:
xxxxxxxxxxcd ~/voice_to_openclawsource .venv/bin/activatepython -m src.openclaw_session_tts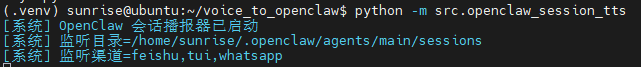
5.1 WhatsApp Scheme
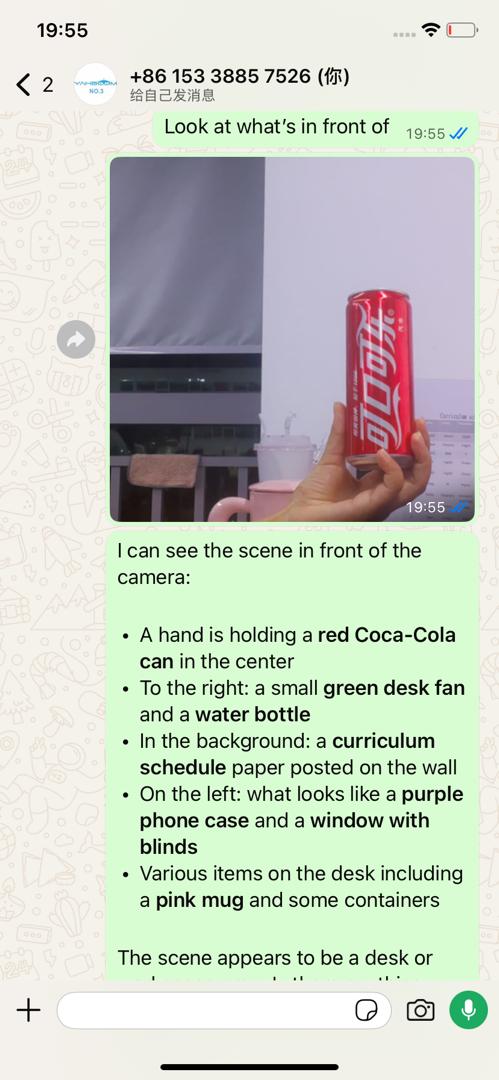
For WhatsApp access steps, please refer directly to [06-Three Conversation Scheme Configuration and Testing]. This section only retains conversation examples suitable for the camera tutorial.
You can restart direct conversation, for example:
See what is in front
Recognize the text in the image
5.2 TUI Scheme
If you have completed the TUI self-check in Part 6, you can continue the conversation by entering the following command in the terminal:
xxxxxxxxxxopenclaw tuiThen you can directly input camera-related instructions, for example:
Take a photo of the current scene
Describe the scene in the lens
Detect if there are any faces
You can add TUI conversation screenshots here.
5.3 Voice Code Scheme
xxxxxxxxxxRequires selection of AI voice interaction module + speaker
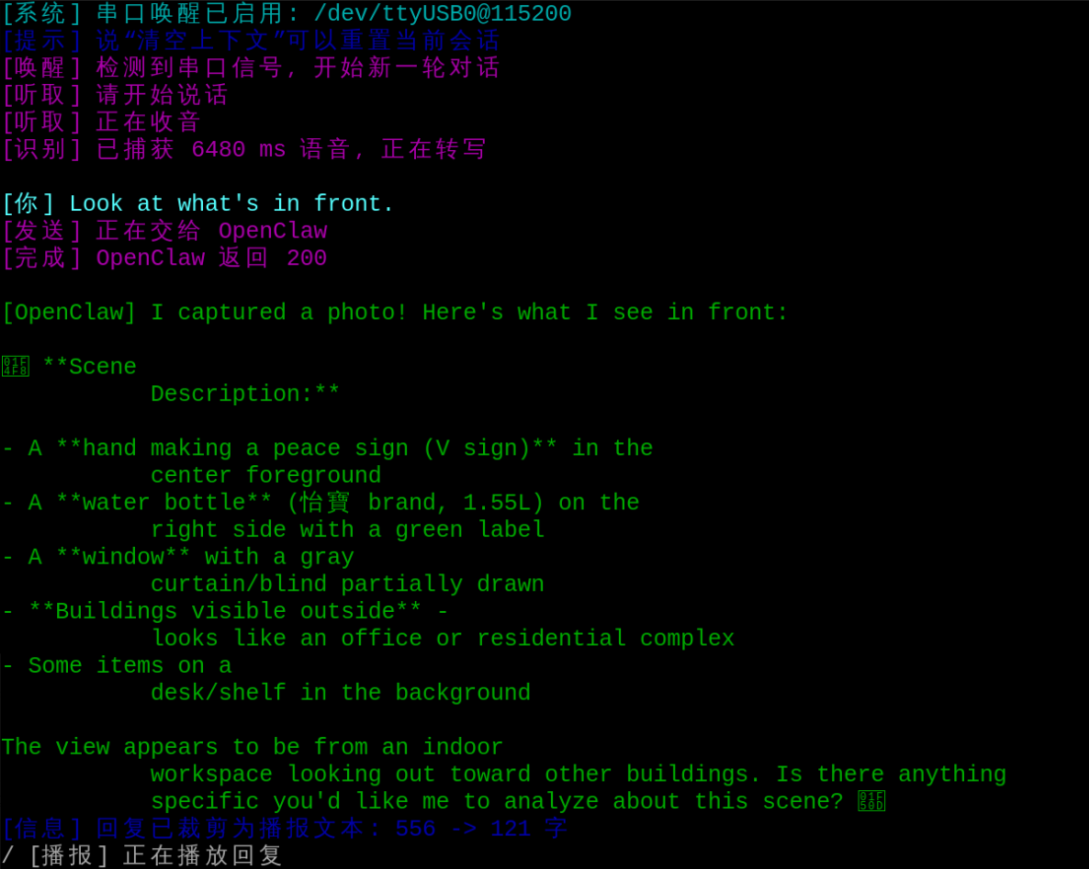
For voice module installation, environment configuration, and basic wake-up process, please refer directly to [04-AI Voice Interaction Configuration]. After wake-up, you can directly speak control content, for example:
Help me take a photo
See what is in front
Help me read the text in the frame
You can add voice wake-up and voice control screenshots here.
6. Comprehensive Cases
Note: The following are conversation demonstrations conducted via openclaw tui. You can also choose WhatsApp or voice methods to complete them.
6.1 Case 1: Photo Archiving
Experiment Objective
Let OpenClaw complete the most basic photography function first and save the image.
Effect Description
After execution, a photo will be generated locally, usually keeping both the current photo file and the latest.jpg alias for the most recent photo. This case is suitable for verifying the image capture pipeline.
Example Instructions
Help me take a photo
Capture the current scene
Take a photo now for record
6.2 Case 2: Scene Description
Experiment Objective
Let OpenClaw provide a brief description of the current scene after taking a photo.
Effect Description
OpenClaw can first complete the photography, then call the visual analysis script to make a one-sentence description of the image content, such as identifying desks, people, food, or common objects.
Example Instructions
See what is in front
Help me describe the current scene
Take a photo and tell me what is mainly in the lens
6.3 Case 3: OCR Table Recognition
Experiment Objective
Let OpenClaw recognize text in the image and organize it into a table.
Effect Description
This case is suitable for photographing labels, cards, packaging, or simple documents, and then extracting the text. It can output plain text or continue to organize it into a table.
Example Instructions
Recognize the text in this image
Take a photo and organize the text into a table
6.4 Case 4: Target Localization and Face Detection
Experiment Objective
Let OpenClaw locate specific targets in the image, or detect if there are any faces in the frame. If a face is detected, the selected photo will default to:
xxxxxxxxxx/home/sunrise/.openclaw/media/csi-camera/annotated/latest-face.png
Effect Description
This type of task is not just about "seeing," but further finding the position of target objects in the image, or recognizing faces and outputting annotation results. It is suitable for interactive displays and simple visual tasks.
Example Instructions
Find the cup in the frame
See if there are any faces
Help me locate the mobile phone on the right side of the desk