yahboom
HomeLearn
Solution
Blog
Online Store
About Us
EN/中文
Raspberry Pi 5📖
00.Quick Start (Must See)
  • 1.Quick Start (Must See)
  • 2.TF card expand capacity
  • 3.Raspberry Pi 5 - 1GB Version Must - See Before Use
01.Introduction to Raspberry PI 5
  • 1. Introduction to Raspberry PI 5
  • 2. Raspberry PI system installation and backup
  • 3. Powering the Raspberry PI 5
  • 4. Startup of Raspberry PI 5
  • 5. Installation and introduction of shell and active radiator
  • 6. GPIO and 40-pin pins
  • 7. Tips for using Raspberry PI 5
  • 8. Raspberry PI PCIe connector
  • 9. MIPI CSI DSI connector
  • 10. UART connector
  • 11. Real-time clock
  • 12. Power over Ethernet (PoE) connector
02.Introduction to common mirror systems
  • 1. Official Raspberry PI system
  • 2. Ubuntu
03.Basic settings of Raspberry Pi
  • 1. Update and upgrade operating system
  • 2.Introduction to raspi-config tool
  • 3.config.txt file description
  • 4.Network Configuration
  • 5.remote access
  • 6.Transfer files remotely
  • 7.Set display resolution and rotation
  • 8.Set screen to sleep
  • 9.Get real-time temperature of Raspberry Pi
  • 10.Play audio and video
  • 11.Using USB camera
  • 12.Using MIPI camera
04.Basic programming course
1. C language programming
  • 1. C language environment construction
  • 2. Print Hello World
2. Python programming
  • 1.Python usage
  • 2.Use APT to install Python packages
  • 3.Python virtual environment
  • 4.GPIO Zero
  • 5.Pin output high and low levels
  • 6.Pin reads high and low levels
  • 7.Pin output PWM
3.Jupyter lab programming
  • 1.Jupyter Lab environment construction
  • 2.Basic use of Jupyter Lab
  • 3.Jupyter Lab plug-in installation
  • 4.Basic use of Jupyter Widgets
05.Advanced AI course
5.Advanced AI gameplay
  • 1. Human pose estimation
  • 2. target detection
  • 3.yolov5
  • 4. Camera display
  • 5. QR code
  • 6. face detection
  • 7. Color recognition
2.Getting started with Open Source CV
  • 1. Introduction to Open Source CV
  • 2. Read and display Open Source CV images
  • 3. Open Source CV image writing
  • 4. Open Source CV image quality
  • 5.Open Source CV pixel operation
3.Open Source CV Geometric Transformations
  • 1. Image resizing
  • 2. Cut the image
  • 3. Image translation
  • 4. Image mirroring
  • 5. Affine transformation
  • 6. Rotate the image
  • 7. Perspective transformation
4.Text Picture Drawing Open Source CV image processing and drawing text line segments
  • 1、Grey Processing
  • 2、image binaryzation
  • 3、edge detection
  • 4、Line segment drawing
  • 5、Rectangle and circle drawing
  • 6、Text image drawing
1.Open Source CV environment setup
  • Open Source CV environment setup
6.YOLOv11 development
  • 1. YOLOv11 environment construction
  • 2. CLI Usage
  • 3. Object Detection
  • 4. Instance Segmentation
  • 5. Pose Estimation
  • 6. Image Classification
  • 7. Oriented Bounding Boxes Object Detection
  • 8. Model conversion
  • 9. Dataset Annotation
  • 10. Model training_conversion
  • 11. Model prediction
7.YOLO26 development
  • 01.YOLO26 environment
  • 02.CLI use
  • 03.Object detection
  • 04.Instance segmentation
  • 05.Pose estimation
  • 06.Image classification
  • 07.Oriented bounding box object detection
  • 08.Model conversion
  • 09.Dataset annotation
  • 10.Model training - conversion
  • 11.Model prediction
06.Mediapipe course
  • 1. Face special effects
  • 2. Face detection
  • 3. Three-dimensional object recognition
  • 4. Paintbrush
  • 5. Finger control
  • 6. Gesture recognition
07.Docker Tutorial
  • 1.Overview and installation
  • 2.Common commands
  • 3.Understand and publish images
  • 4.Hardware interaction data processing
  • 5.Enter docker container
  • 6.Update docker images
  • 7. docker container to install ROS using accessories
08.ROS1 advanced tutorial
1.ROS1 basic course
  • 1.ROS introduction
  • 2.ROS installation
  • 3.ROS common command tools
  • 4.ROS workspace
  • 5.ROS function package
  • 6.ROS node
  • 7.ROS topic publisher
  • 8.ROS topic subscribers
  • 9.ROS service client
  • 10.ROS service server
  • 11.ROS action client
  • 12.ROS action server
  • 13.ROS custom message reception
  • 14.ROS-launch file
  • 15.ROS-TF transformation
  • 16.ROS parameter service
  • 17.ROS-rviz use
  • 18.ROS-rqt tool usage
  • 19.Topic message recording and playback
  • 20.urdf model introduction
  • 21.gazebo introduction
  • 22.ROS distributed communication
2.ROS1 vision application
  • 0.Precautions
  • 1.AR vision
  • 2.AR QR code
  • 3.ROS+Opencv basics
  • 4.Face recognition
  • 5.harris corner detection
  • 6.Target tracking algorithm
  • 7.Contour moment
  • 8.Polygon outline
  • 9.Discrete fourier transform algorithm
  • 10.Edge detection algorithm
  • 11.Face detection algorithm
  • 12.Optical flow detection algorithm
  • 13.Contour detection
  • 14.General contour detection
  • 15.Feature point tracking
  • 16.HLS color filtering
  • 17.Hough circle detection
  • 18.Hough linear detection
  • 19.HSV color filtering
  • 20.LK optical flow algorithm
  • 21.detection algorithm
  • 22.Phase dependent displacement detection
  • 23.Image pyramid sampling algorithm
  • 24.RGB color filtering
  • 25.Clear background detection algorithm
  • 26.Simplified optical flow algorithm
  • 27.Simple filter
  • 28.Threshold image processing
  • 29.Watershed segmentation algorithm
09.ROS2 advanced tutorial
1.ROS2 basic course
  • 1. Introduction to ROS2
  • 2.ROS2 install Humble
  • 3.ROS2 development environment
  • 4.ROS2 workspace
  • 5.ROS2 function package
  • 6.ROS2 node
  • 7.ROS2 topic communication
  • 8.ROS2 service communication
  • 9.ROS2 action communication
  • 10.ROS2 custom interface message
  • 11.ROS2 parameter service case
  • 12.ROS2 meta-function package
  • 13.ROS2 distributed communication
  • 14.ROS2 DDS
  • 15.ROS2 time related API
  • 16.ROS2 common command tools
  • 17.ROS2 rviz2 use
  • 18.ROS2 rqt toolbox
  • 19.ROS2 Launch startup file configuration
  • 20.ROS2 recording and playback tool
  • 21.ROS2 URDF model
  • 22.ROS2 Gazebo simulation platform
  • 23.ROS2 TF2 coordinate transformation
2.ROS2 vision application
  • 0.Precautions
  • 1.Opencv basic course
  • 2.ROS+opencv application
  • 3.QR code creation and recognition
  • 4.AR vision
  • 5.Interesting gameplay of mediapipe
10.Offline AI model coursenew
Offline large model (Text Interaction)
  • 0. AI large model image description
  • 1. Deployment of large AI model environments
  • 2. Switch Chinese input method
  • 3. Installation of large model dialogue platform
  • 4. Meta AI Llama 3.2 model
  • 5. Alibaba Cloud Qwen3 Model
  • 6. Microsoft Phi-4-mini model
  • 7. DeepSeek DeepSeek-R1 model
  • 8. Alibaba Cloud Qwen2.5vl Visual Multimodal Large Model
  • 9. Google Gemma3 Visual Multimodal Large Model
  • 10. Llava Visual Multimodal Large Model
  • 11.MiniCPM-V Visual Multimodal Large Model
  • 12. Multimodal Visual Understanding Applications
  • 13. Multimodal Text-Based Image Application
  • 14. Multimodal Video Analysis Application
  • 15. Multimodal visual positioning applications
  • 16. Multimodal table scanning application
  • 17. Multimodal Autonomous Agent Application
Offline large model (Voice Interaction)
  • 0. Voice Interaction Hardware Connection (Must Read)
  • 1. Offline speech-to-text (ASR)
  • 2. Offline Text-to-Speech (TTS)
  • 3. AI large model voice interaction
  • 4. Multimodal visual understanding and voice interaction
  • 5. Multimodal Text-Based Image Application
  • 6. Multimodal Video Analysis Application
  • 7. Multimodal visual positioning applications
  • 8. Multimodal table scanning application
  • 9. Multimodal Autonomous Agent Applications
  • 10. AI large model offline voice assistant
11.Online AI model coursenew
Online large model (text interaction)
  • 1.OpenRouter Large Model API Aggregation Platform
  • 2. Multimodal Visual Understanding Applications
  • 3. Multimodal visual positioning applications
  • 4. Multimodal table scanning application
  • 5. Multimodal Autonomous Agent Applications
Online large model (voice interaction)
  • 0. Voice Interaction Hardware Connection (Must Read)
  • 1. Online speech-to-text (ASR)
  • 2. Online Text-to-Speech (TTS)
  • 3. AI large model voice interaction
  • 4. Multimodal visual and voice interaction
  • 5. Multimodal visual positioning applications
  • 6. Multimodal table scanning application
  • 7. Multimodal Autonomous Agent Applications
  • 8. AI large model online voice assistant
12.OpenClaw Deployment and Basic Usagenew
  • 01. OpenClaw Deployment
  • 02. OpenClaw WhatsApp Plugin Application
  • 03. OpenClaw WebChat Interaction
  • 04. OpenClaw TUI Interaction
  • 05. OpenClaw Tools Introduction
  • 06. OpenClawGate Gateway User Manual
  • 07. OpenClaw Features Overview
  • 08. OpenClawHub Introduction (Skill Installation)
  • 09. OpenClaw Application - File Management
  • 10. OpenClaw Application - Camera
  • 11. OpenClaw Application - Browser Control
  • 12. OpenClaw Application - Script Execution
  • 13. OpenClaw Application - AI Programming (Peripheral & GPIO Control)
  • 14. OpenClaw Application - Dedicated AI Assistant
13.OpenClaw Advanced Developmentnew
1.Preparation Before Use
  • 01. Peripheral Hardware Configuration
  • 02. OpenClaw API-KEY Configuration
  • 03. OpenClaw Model Switching
  • 04. OpenClaw Prompts
  • 05. AI Voice Interaction Configuration
  • 06. 3D Configuration Tests
2.OpenClaw AI Programming Peripheral Control
  • 1. Servo Control
  • 2. RGB Strip
  • 3. OLED Display
  • 4. Temperature and Humidity Sensor
  • 5. Camera Application
  • 6. AI Script Peripheral Control
3.OpenClaw Peripheral Integration Applications
  • 1. Plant Care Assistant
  • 2. AI Calorie Estimation
  • 3. AI Rock Paper Scissors Game
  • 4. AI Pet
  • 5. AI Weather Station
  • 6. Temperature and Humidity Dashboard
  • 7. Scheduled Tasks
Download
  • SystemFile
  • Code
  • SoftWare
  • 3D_Model_File
  • GuideManual
Download ZIP

Welcome to Raspberry Pi 5 repository

1. Offline speech-to-text (ASR)

1. Offline Speech-to-Text (ASR)

1. Offline Speech-to-Text (ASR)1. Concept Introduction1.1 What is "ASR"?1.2 Implementation Principles1. Acoustic Model2. Language Model3. Pronunciation Dictionary4. Decoder5. End-to-End ASR2. Code AnalysisKey Code1. Speech Processing and Recognition Core (largemodel/largemodel/asr.py)2. VAD smart recording (largemodel/largemodel/asr.py)Code Analysis3. Practical Operations3.1 Configuring Offline ASR3.2 Launch and test the function


Note: Due to performance limitations, the Raspberry Pi 5 2GB version cannot run offline.The Raspberry Pi 5 1GB version does not have a large model package and cannot run this case. Please refer to the online tutorial for the larger model.

1. Concept Introduction

1.1 What is "ASR"?

ASR (Automatic Speech Recognition) is a technology that converts human speech signals into text. It is widely used in smart assistants, voice command control, telephone customer service automation, and real-time subtitle generation. The goal of ASR is to enable machines to "understand" human speech and convert it into a form that computers can process and understand.

1.2 Implementation Principles

The implementation of an ASR system primarily relies on the following key technical components:

1. Acoustic Model

  • The acoustic model is responsible for converting the input sound signal into phonemes or subword units. This typically involves feature extraction, such as using Mel-Frequency Cepstral Coefficients (MFCCs) or filter banks to represent the audio signal. These features are then fed into a deep neural network (DNN), convolutional neural network (CNN), recurrent neural network (RNN), or the more advanced Transformer architecture for training, learning how to map audio features to corresponding phonemes or words.

2. Language Model

  • A language model predicts the most likely next word given the previous context, thereby improving recognition accuracy. It is trained on large amounts of text data to understand which word sequences are most likely to occur.

  • Common language models include n-gram models, RNN-based language models (LMs), and the more popular Transformer-based language models.

3. Pronunciation Dictionary

  • A pronunciation dictionary provides a mapping between words and their corresponding pronunciations. This is crucial for connecting the acoustic model and language model, as it allows the system to understand and match the sounds it hears to known pronunciation rules.

4. Decoder

  • The decoder's task is to find the most likely word sequence as output given the acoustic model, language model, and pronunciation dictionary. This process typically involves complex search algorithms, such as the Viterbi algorithm or graph-based search methods, to find the optimal path.

5. End-to-End ASR

  • With the advancement of deep learning, end-to-end ASR systems have emerged. These systems attempt to learn text output directly from raw audio signals, without requiring explicit acoustic models, pronunciation lexicons, and separate language models. These systems are often based on sequence-to-sequence (Seq2Seq) frameworks, using, for example, attention mechanisms or the Transformer architecture, significantly simplifying the complexity of traditional ASR systems.

In general, modern ASR systems achieve efficient and accurate human speech-to-text conversion by combining the aforementioned components and leveraging large datasets and powerful computing resources for training. With technological advancements, the performance of ASR systems continues to improve, and their application scenarios are becoming increasingly broad.


2. Code Analysis

Key Code

1. Speech Processing and Recognition Core (largemodel/largemodel/asr.py)

​x
# From largemodel/largemodel/asr.py
def kws_handler(self)->None:
    if self.stop_event.is_set():
        return      

    if self.listen_for_speech(self.mic_index):
        asr_text = self.ASR_conversion(self.user_speechdir)  # Perform ASR conversion
        if asr_text =='error':  # Check if ASR result length is less than 4 characters
            self.get_logger().warn("I still don't understand what you mean. Please try again")
            playsound(self.audio_dict[self.error_response])  # Error response
        else:
            self.get_logger().info(asr_text)
            self.get_logger().info("okay😀, let me think for a moment...")
            self.asr_pub_result(asr_text)  # Publish ASR result            
    else:
        return

def ASR_conversion(self, input_file:str)->str:
    if self.use_oline_asr:
        result=self.modelinterface.oline_asr(input_file)
        if result[0] == 'ok' and len(result[1]) > 4:
            return result[1]
        else:
            self.get_logger().error(f'ASR Error:{result[1]}')  # ASR error.
            return 'error'
    else:
        result=self.modelinterface.SenseVoiceSmall_ASR(input_file)
        if result[0] == 'ok' and len(result[1]) > 4:
            return result[1]
        else:
            self.get_logger().error(f'ASR Error:{result[1]}')  # ASR error.
            return 'error'

2. VAD smart recording (largemodel/largemodel/asr.py)

xxxxxxxxxx
# From largemodel/largemodel/asr.py
def listen_for_speech(self,mic_index=0):
    p = pyaudio.PyAudio()   # Create PyAudio instance. 
    audio_buffer = []       # Store audio data. 
    silence_counter = 0     # Silence counter. 
    MAX_SILENCE_FRAMES = 90  # Stop after 900ms of silence (30 frames * 30ms)
    speaking = False  # Flag indicating speech activity.
    frame_counter = 0  # Frame counter. 
    stream_kwargs = {
        'format': pyaudio.paInt16,
        'channels': 1,
        'rate': self.sample_rate,
        'input': True,
        'frames_per_buffer': self.frame_bytes,
    }
    if mic_index != 0:
        stream_kwargs['input_device_index'] = mic_index

    # Prompt the user to speak via the buzzer. 
    self.pub_beep.publish(UInt16(data = 1))
    time.sleep(0.5)
    self.pub_beep.publish(UInt16(data = 0))

    try:
        # Open audio stream. 
        stream = p.open(**stream_kwargs)
        while True:
            if self.stop_event.is_set():
                return False 
    
            frame = stream.read(self.frame_bytes, exception_on_overflow=False)  # Read audio data. 
            is_speech = self.vad.is_speech(frame, self.sample_rate)  # VAD detection. 

            if is_speech:
                # Detected speech activity. 
                speaking = True
                audio_buffer.append(frame)
                silence_counter = 0
            else:
                if speaking:
                    # Detect silence after speech activity. 
                    silence_counter += 1
                    audio_buffer.append(frame)  # Continue recording buffer.
                    
                    # End recording when silence duration meets the threshold. 
                    if silence_counter >= MAX_SILENCE_FRAMES:
                        break
            frame_counter += 1
            if frame_counter % 2 == 0:
                self.get_logger().info('1' if is_speech else '-')
                # Real-time status display.
    finally:
        stream.stop_stream()
        stream.close()
        p.terminate()

    # Save valid recording (remove trailing silence). 
    if speaking and len(audio_buffer) > 0:
        # Trim the last silent part. 
        clean_buffer = audio_buffer[:-MAX_SILENCE_FRAMES] if len(audio_buffer) > MAX_SILENCE_FRAMES else audio_buffer
        
        with wave.open(self.user_speechdir, 'wb') as wf:
            wf.setnchannels(1)
            wf.setsampwidth(p.get_sample_size(pyaudio.paInt16))
            wf.setframerate(self.sample_rate)
            wf.writeframes(b''.join(clean_buffer))
            return True

Code Analysis

ASR (speech-to-text) functionality is provided by the ASRNode node (asr.py). This node is responsible for recording, converting, and publishing audio.

  1. Audio Recording (listen_for_speech):

    • This function uses the pyaudio library to capture the audio stream from the microphone.

    • It integrates the webrtcvad library for voice activity detection (VAD). The function loops through audio frames and uses vad.is_speech() to determine whether each frame contains human voice.

    • When speech is detected, the data is written to a buffer. Recording stops when sustained silence (defined by MAX_SILENCE_FRAMES) is detected.

    • Finally, the audio data in the buffer is written to a .wav file in the self.user_speechdir directory.

  2. Backend Selection and Execution (ASR_conversion):

    • The kws_handler function calls the ASR_conversion function after successful recording.

    • This function determines which backend implementation to call by reading the ROS parameter use_oline_asr (a Boolean value).

    • If false, the self.modelinterface.SenseVoiceSmall_ASR method is called for local recognition.

    • If true, the self.modelinterface.oline_asr method is called for online recognition.

    • This function passes the audio file path as a parameter to the selected method and processes the returned result.

  3. Result Publishing (asr_pub_result):

    • After ASR_conversion returns valid text, kws_handler calls the asr_pub_result function.

    • This function encapsulates a text string in a std_msgs.msg.String message and publishes it to the /asr topic via the ROS publisher.

3. Practical Operations

3.1 Configuring Offline ASR

To enable offline ASR, you need to correctly configure the yahboom.yaml file and ensure that the local model is correctly placed.

First, enter the following command in the terminal to enter the Docker container:

xxxxxxxxxx
./ros2_docker.sh

If you need to enter the same Docker container and run other commands later, simply enter ./ros2_docker.sh again in the host terminal.

  1. Open the configuration file:

    xxxxxxxxxx
    vim ~/yahboom_ws/src/largemodel/config/yahboom.yaml
  2. Modify/confirm the following key configuration:

    xxxxxxxxxx
    asr:                                    #Voice node parameters
      ros__parameters:
        # ...
        use_oline_asr: False                # CRITICAL: Must be set to False to enable offline ASR
        mic_serial_port: "/dev/ttyUSB0"     # Microphone serial port alias
        mic_index: 0                        # Microphone device index
        language: 'zh'                      # asr language, 'zh' or 'en'
        regional_setting : "China"

    Make sure use_oline_asr is set to False to use the local model.

    In the terminal, enter ls /dev/ttyUSB* to check if the USB device number assigned to the voice module is USB0. If not, replace the 0 in the configuration file with your own device number.

    Select "zh" for Chinese and "en" for English.

    Also, specify the path to the offline model in large_model_interface.yaml.

    Open the file in the terminal.

    xxxxxxxxxx
    vim ~/yahboom_ws/src/largemodel/config/large_model_interface.yaml

    Find the configuration related to local_asr_model.

    xxxxxxxxxx
    # large_model_interface.yaml
    ## Offline speech recognition (Offline ASR)
    local_asr_model: "/root/yahboom_ws/src/largemodel/MODELS/asr/SenseVoiceSmall"  # Local ASR model path

3.2 Launch and test the function

  1. After entering the Docker container, run the following command:

xxxxxxxxxx
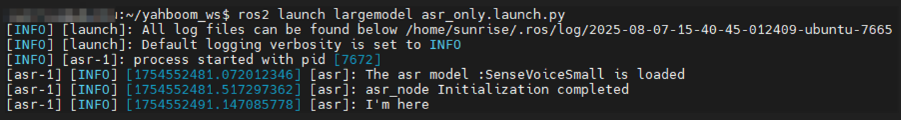
ros2 launch largemodel asr_only.launch.py
  1. Test: Say "Hi,yahboom" into the microphone. It will respond, "I'm here." Then you can start speaking. Finally, the recorded audio will be converted into text and printed on the terminal. image-20250807154240917
Voice Interaction Hardware Connection (Must Read)
Offline Text-to-Speech (TTS)

COMPANY

  • About us
  • Team Style
  • Blog

LEARNING & EXPLORATION

  • Tutorials
  • Edge AI hardware
  • Educational robots
  • Embedded intelligent hardware

WHERE TO BUY

  • Yahboom Online Store
  • Amazon
  • Alibaba
  • AliExpress
  • Mercado

TECHNOLOGY SUPPORT

  • Email: support@yahboom.com

BE A DISTRIBUTOR

  • Email: sales@yahboom.com
QR Code

Copyright © 2017-2026 Yahboom. All Rights Reserved.

EN/中文