Welcome to Jetson Orin NANO Developer Kit repository
04.Alibaba Cloud - Qwen model
Qwen3
Qwen31. Model Size2. Performance3. Using Qwen33.1. Running Qwen33.2. Starting a Conversation3.3. Ending the ConversationReferences
Demo Environment
Development board: Jetson Orin series mainboard
Note: Due to performance limitations, the Jetson Orin Nano 4GB needs to run the small-parameter version. The 8B model of qwen cannot be used on Jetson Orin Nano 8GB and lower memory
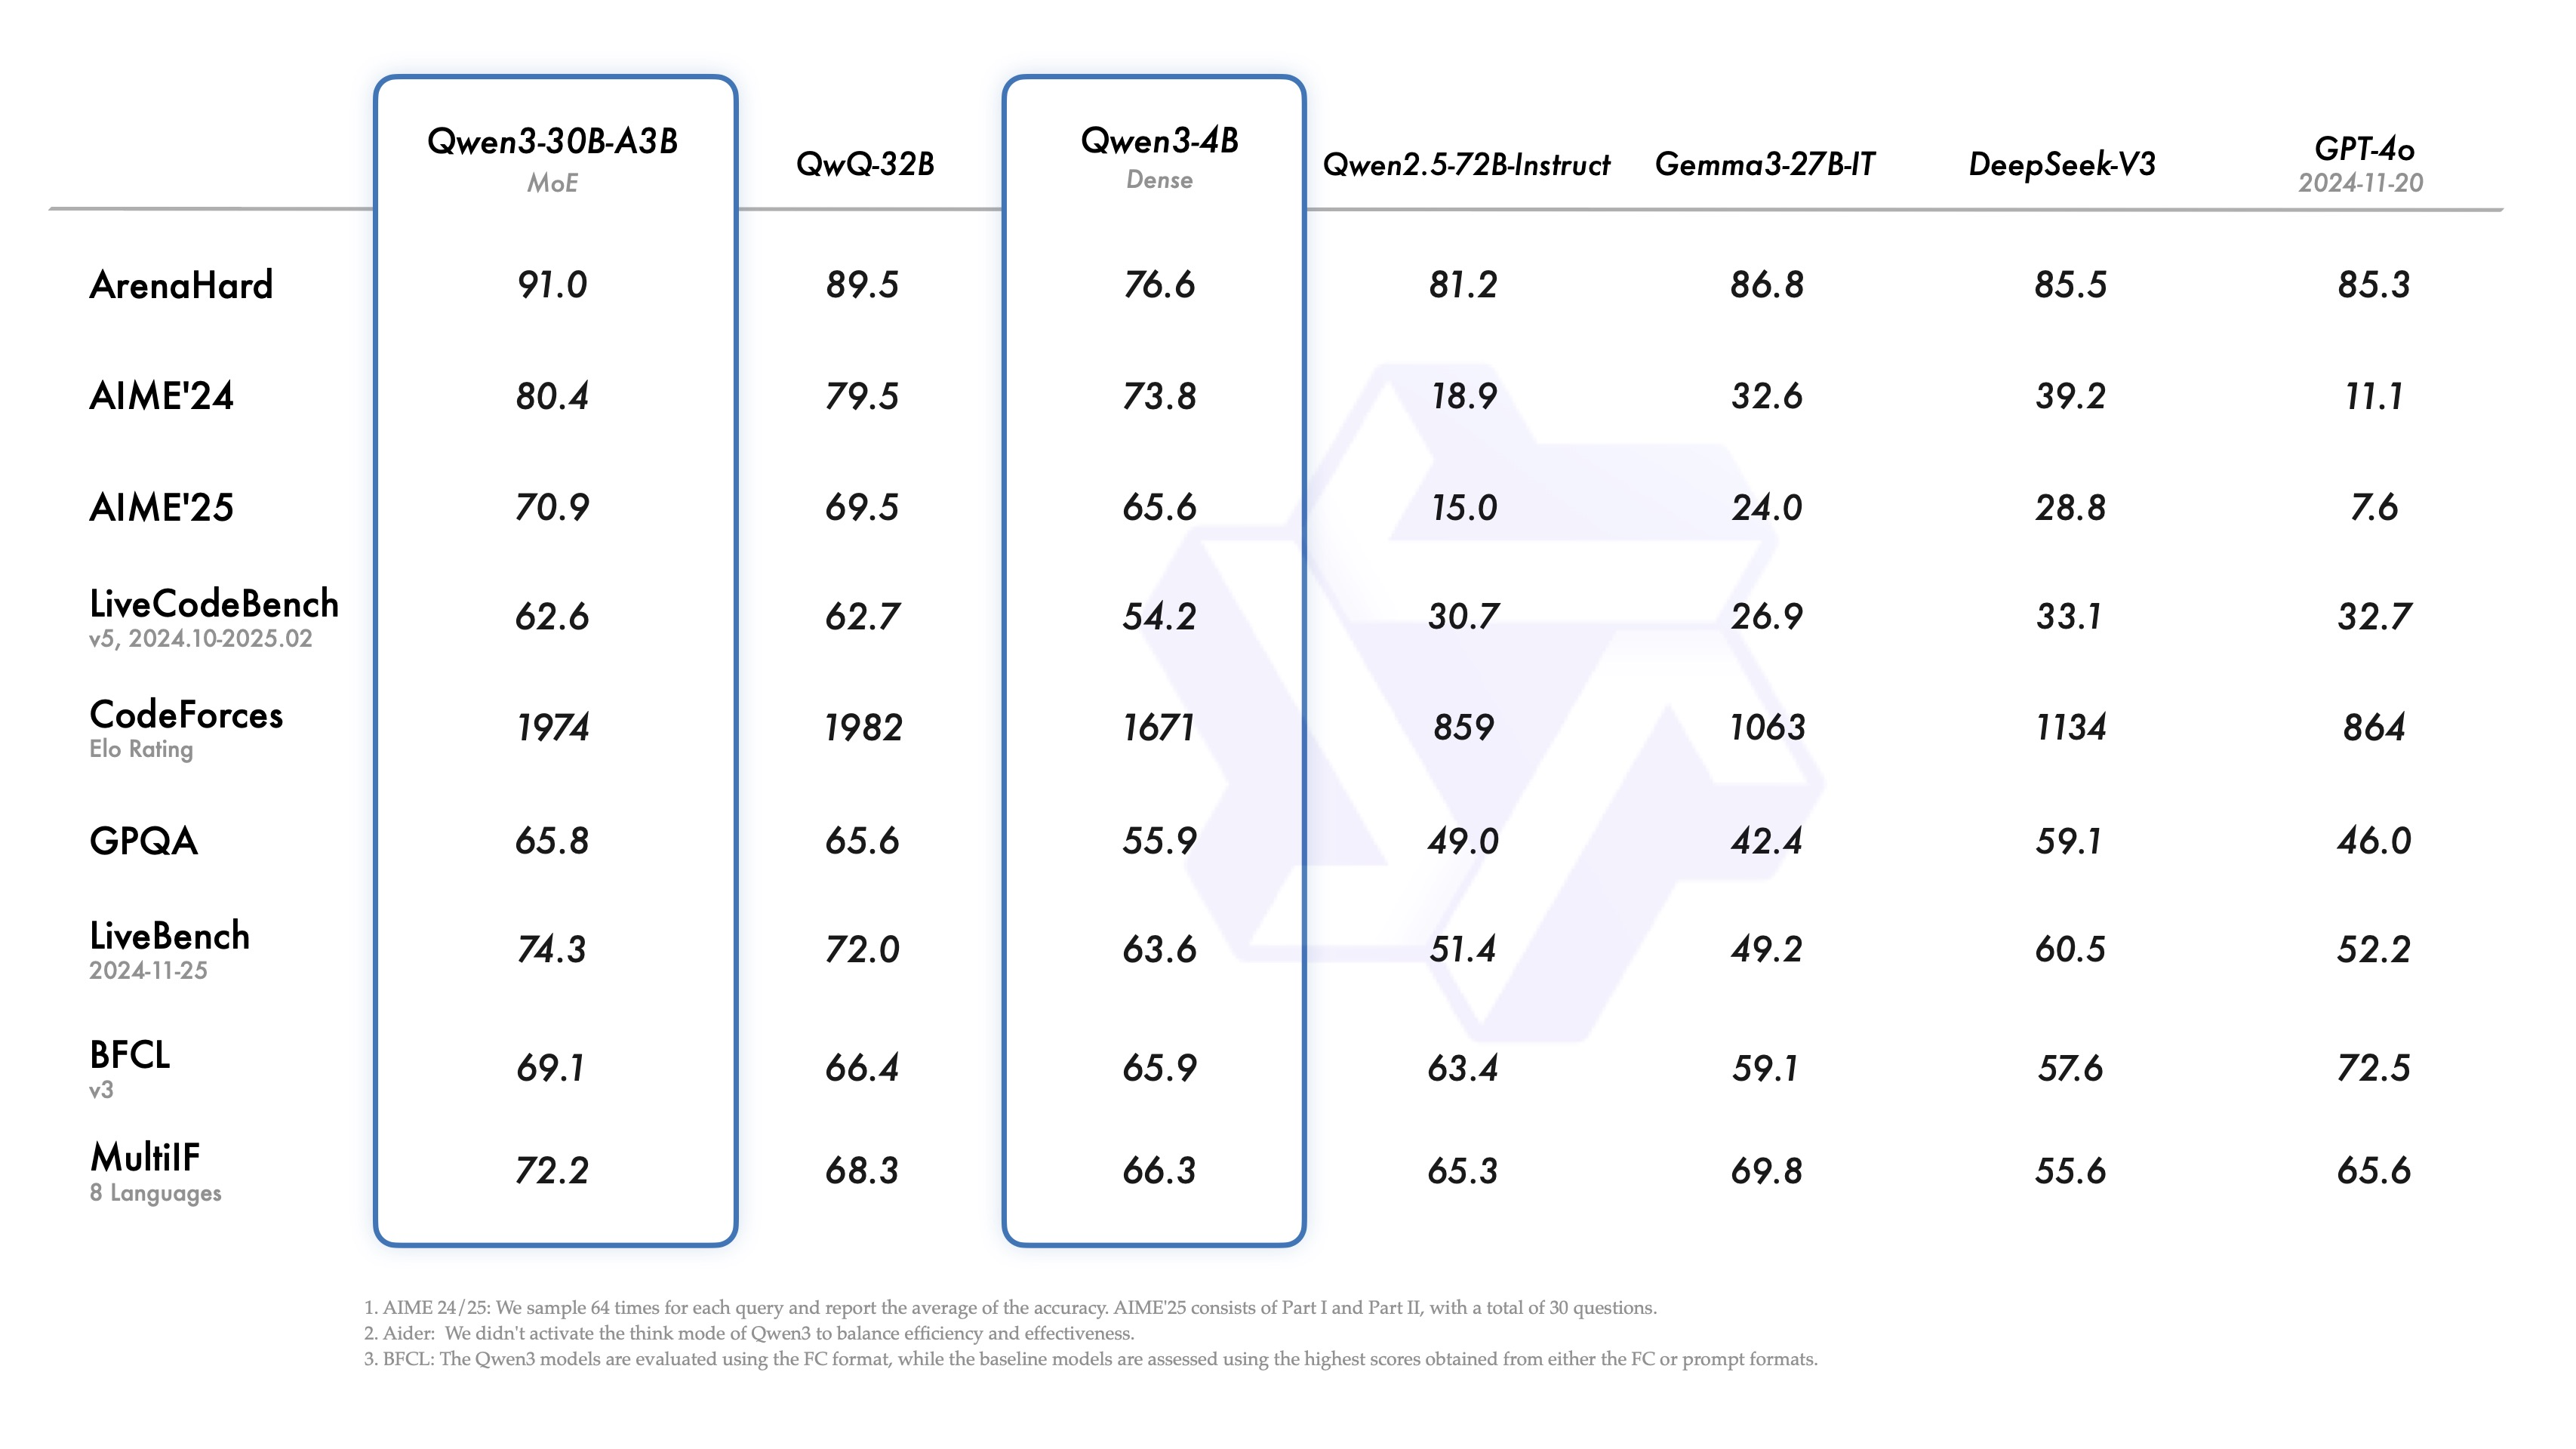
Qwen 3 is the latest generation of large language models in the Qwen series, providing a complete set of dense and mixture-of-experts (MoE) models.
1. Model Size
| Model | Size |
|---|---|
| qwen3:0.6b | 523MB |
| qwen3:1.7b | 1.4GB |
| qwen3:4b | 2.6GB |
| qwen3:8b | 5.2GB |
2. Performance

3. Using Qwen3
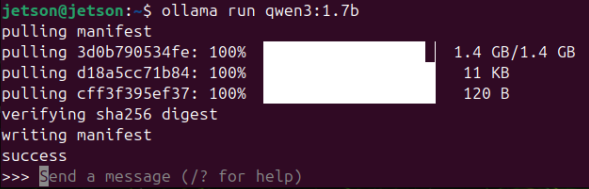
3.1. Running Qwen3
Run the model with the run command; if it is not downloaded yet, Ollama pulls it automatically:
ollama run qwen3:1.7b
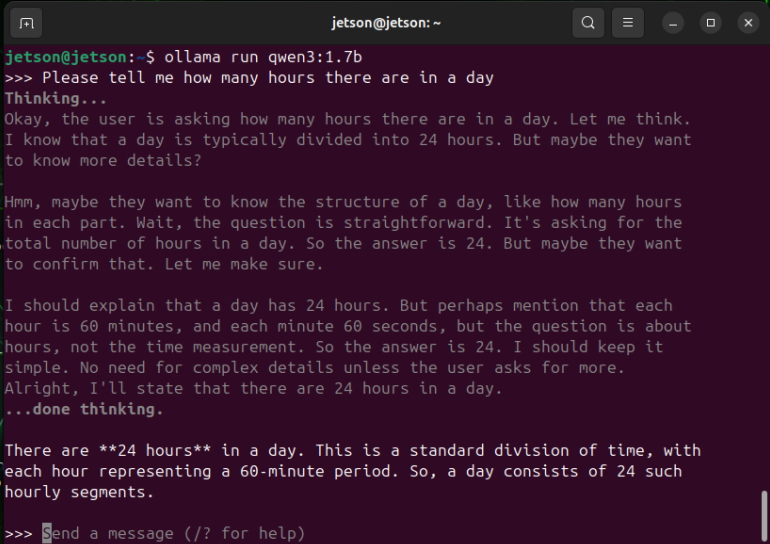
3.2. Starting a Conversation
xxxxxxxxxxPlease tell me how many hours there are in a day
Response time depends on the hardware; please be patient.
3.3. Ending the Conversation
Use the Ctrl+d shortcut or /bye to end the conversation!
References
Ollama
Official website: https://ollama.com/
GitHub: https://github.com/ollama/ollama
Qwen3
GitHub: https://github.com/QwenLM/Qwen3
Ollama corresponding model: https://ollama.com/library/qwen3